

Three subjects that were fairly obscure when I chose them as specialties as a student were programming tools, cybersecurity, and formal methods. Strangely (to me, at least), they’re all having a moment now in connection to generative AI. This article covers an interesting mix of challenge and opportunity at their intersection. The opportunity will relate to our persistent larger story of very scalable automation for writing trustworthy code.
The AI-safety community has at least for some time (decades) talked around the possibility of powerful AI finding new security vulnerabilities in important code. The 2023 GPT-4 Technical Report called out that usage mode as a risk. In 2026, Anthropic prepared to release a new LLM named Mythos, which they had become worried was too good at finding vulnerabilities. As a result, instead of starting with a broad release, they initiated Project Glasswing, which only shared Mythos with a modest set of big-name tech companies, to get their help understanding the cybersecurity implications. Eventually, a weakened version was released widely under the name Fable. Then the next twist was the U.S. government basically declaring that even Fable was too dangerous and couldn’t be exported to other countries, a restriction so hard to implement that Anthropic removed Fable access for everyone.
Eventually, Fable was allowed back into the wild, but the whole saga got many more people thinking about cybersecurity risks from powerful AI. There was also a more recent headline-grabbing story, about how an improperly configured model-testing environment led to an OpenAI agent compromising a Hugging Face server. Let’s fight the gravitational pull of sci-fi sensationalism and instead talk through the fundamental changes to how software engineering should be done.
Deep Learning Finds Security Bugs
The problem is actually grounded in a mix of technology and economics. Standard software-development methods have always allowed security-critical bugs to survive unnoticed in important programs. Well before generative AI went big, there was a thriving market in zero-day vulnerabilities: each a security bugs that someone had found but that was not yet known to the owners of a program. A bad actor canonically buys a zero-day and uses it to stage one or a handful of attacks. Markets in zero-days were studied, and bugs in important programs would generally go for thousands to hundreds of thousands of U.S. dollars each.
Lurking bugs in popular software programs are one example of the antipattern of security through obscurity, where the maintainers of a system assume that aspects of the system are obscure enough that no one will figure out their security vulnerabilities. Even an open-source program can benefit from obscurity, where the code base is generally complex enough that few outsiders can decipher it well enough to pinpoint vulnerabilities. The less popular a software package, the more it benefits from obscurity. Obscurity is even more powerful for closed-source programs, which may be distributed only in binary form. Then a process called reverse engineering is needed to recover even the level of detail found in normal source code. The bad news is that generative AI is also proving to be useful for reverse engineering, so the obscurity bonus for closed-source software is eroding.
There used to be a major bottleneck in finding zero-days: the time of a scarce population of security experts. If the market values bugs in a particular program at a low enough level, the experts won’t spend their time finding those bugs. The emerging problem may be clear from that last sentence: if vulnerability discovery can be automated by LLMs instead, it often becomes economical to set them loose on relatively obscure code bases and still come out ahead. We have lost the old defense that most code isn’t economically important enough that its bugs are worth enough to justify the cost of finding them. Roughly speaking, the cost of vulnerability-finding is heading toward becoming negligible, as providers of LLM services optimize their offerings.
On the face of it, this development brings clear bad news for “the good guys,” the well-meaning creators and maintainers of software packages. Innocent coding mistakes frequently create security bugs, and it is no longer safe to assume that those bugs will be obscure enough that no one will invest in finding them. However, this state of affairs pretty directly implies a great way for software engineers to defend themselves.
Assume an attacker has a cheap, automated way to find security vulnerabilities. Then we can transform that method into an effective way for software developers to find vulnerabilities before releasing code – maybe even before allowing it to pass continuous integration (the sanity checks often placed between new code and other software developers on a team).
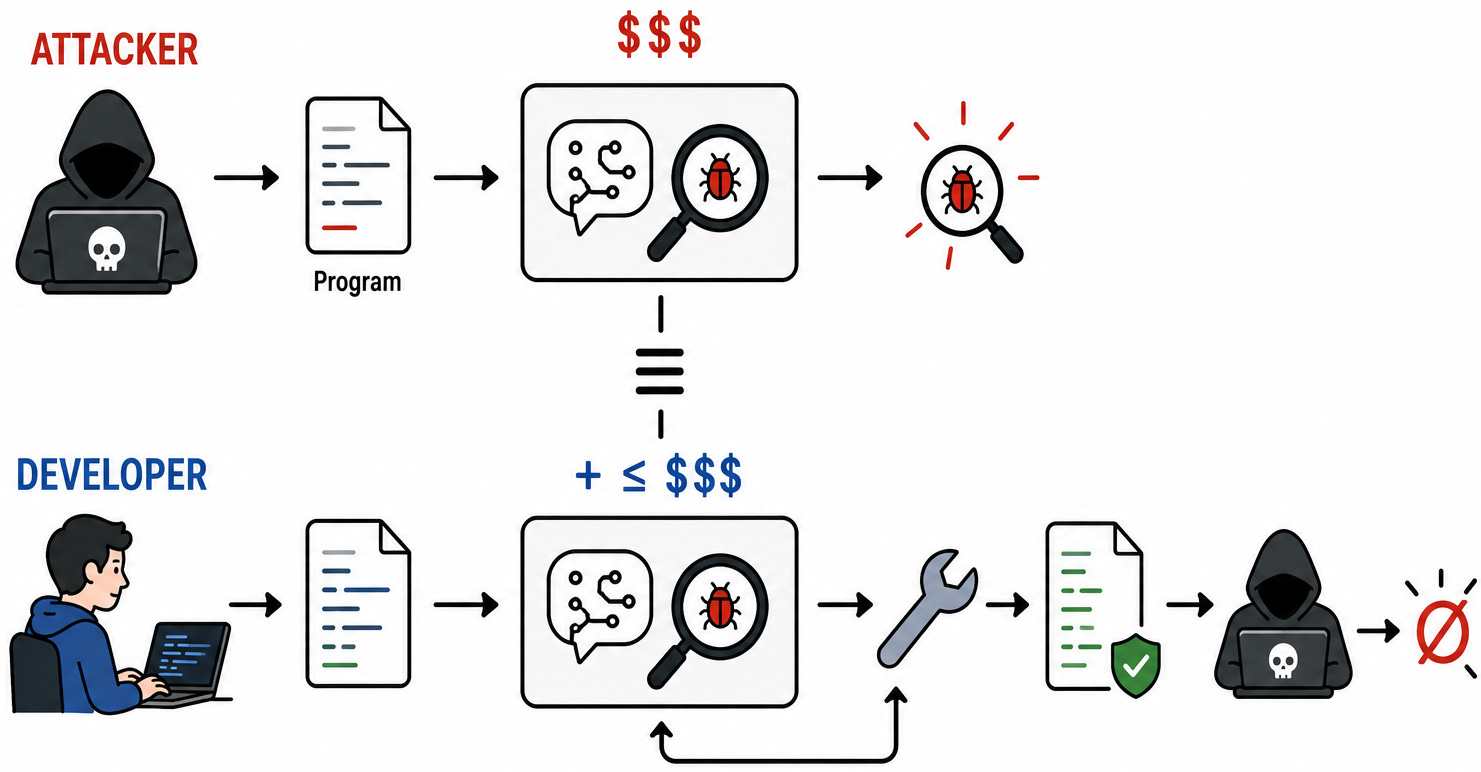
Now assume that the attacker still has a cost-effective way to find bugs using LLMs or any other readily available automation. It follows that the software developers can adopt the same tooling as part of their quality assurance, and it remains cost-effective. That is, defenders are in good shape so long as they have access to roughly the same scanning tools as the attackers. We might need to assume that legitimate software projects are at least as well-funded as the attackers, which isn’t always true, though it’s increasingly likely to be true enough as the cost of LLM-based methods drops. For maximum benefit, we must also assume that attackers don’t get head starts, with earlier access to new automation. (We’ll come shortly to addressing the further asymmetry that attackers often win over defenders when both sides can only run tools that generate bug ideas without guarantees of completeness.)
If we are somehow able to ensure those two assumptions hold, then (modulo the last parenthetical) we are in even better security shape than before generative AI took the stage. There is a one-time adjustment process to bring these new tools into all existing and new projects, which admittedly is a large cost globally, and we will return to that challenge at the end of this article and especially in the next one. However, we should remain worried about the possibility that attackers repeatedly manage to get early access to new bug-finding tools, due to the same kinds of arms-race dynamics that arise for communication speed in high-frequency trading. Is there any hope for a security check to end all security checks, where we don’t have to worry that future tool generations will find bugs that their predecessors missed? So long as we rely on the mysterious black boxes that are deep-learning models, it seems we’ll always have to deal with rare but consequential mistakes, and security is a domain where even rare mistakes can be quite consequential indeed.
Enter Formal Verification
Readers who have been following along in the series are probably not surprised that I now bring up formal verification as the ideal solution! That is, if we produce machine-checked mathematical proofs that programs have the right security properties, those proofs cover all possible execution scenarios, and attackers can’t find bugs later, regardless of the growing quality of their analysis tools.
Let me be a little more specific. LLM vulnerability-finders are not different in kind from a variety of security-scanning tools that were already standard years ago, including the category of static application security testing (SAST). This whole category of bugfinding is often understood probabilistically, generating “good guesses” about where true problems lie. If any guarantee is present about finding all security issues in some category, it is usually paired with generating many false positives, to the point where developers hesitate to wade through them all and may just refuse to use the tool. (After all, we can write a guaranteed-sound “bugfinder” that just accuses every line of code of looking fishy!) The upshot is that automatic methods are not able to draw attention to all security issues; we should think of them as stochastically missing important bugs every now and then. Over time, as new tools are released (including those based on LLMs), they may converge toward reliably reporting all vulnerabilities. However, it is very hard to become convinced that, at a point in time, there does not remain an important gap of undetected issues, which attackers remain incentivized to find and exploit.
Formal verification can fill this gap, guaranteeing coverage of all instances of a bug category, with no inherent requirement to produce false positives. There remains a common objection by savvy practitioners (beyond the cost of proof-writing, which we’ll save for later posts): are we really so sure we know how to spell out what security means, with enough mathematical precision? The good news here is that there are a number of established counterintuitive phenomena of formal methods to help out. For one thing, proving almost any interesting property of a program tends to rule out some of the worst security problems. For another thing, though it may be hard to come up with the right properties to prove of a component in isolation, integrating proofs of different components is extremely effective at finding specification mistakes. The same techniques also help protect against bugs in all system infrastructure that an application depends on, because infrastructure layers can also be verified, and proofs can be composed across layers.
Still, there’s no doubt about it: writing specifications is a nontrivial engineering activity. Nonetheless, there is a force multiplier in specification-writing: it can contribute much more to security than careful software development, per unit of effort. Consider the following two stylized scenario variants, maintaining a software package with and without formal verification.
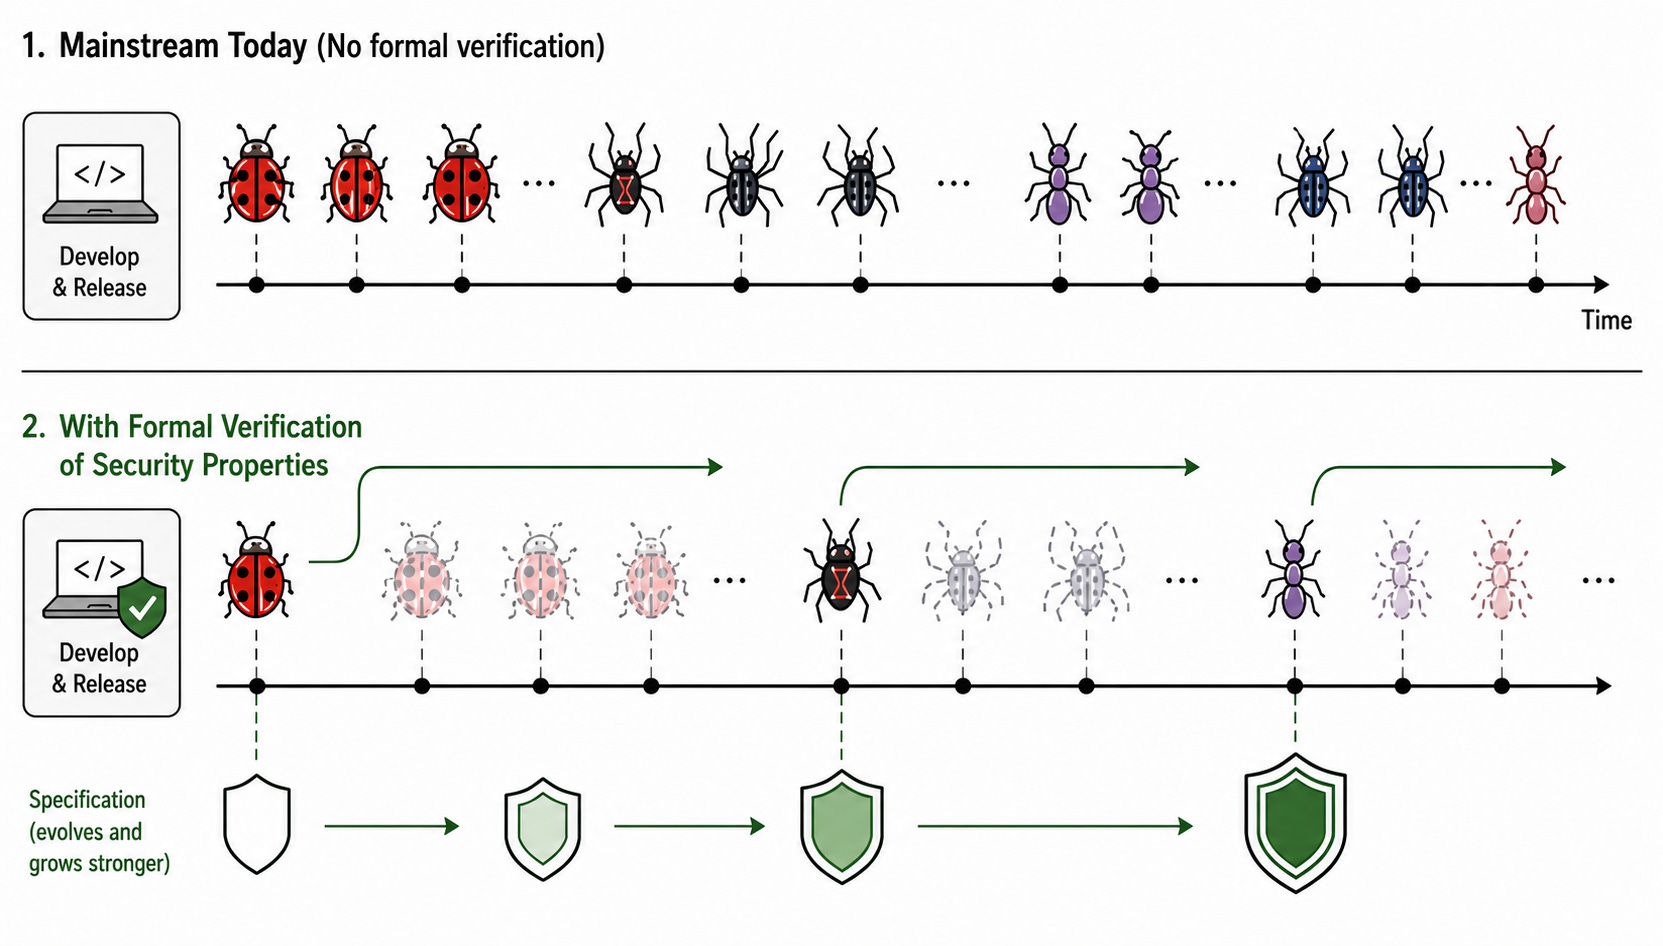
The upper scenario represents the mainstream approach today, where new security bugs keep popping up. Many of them are similar to past bugs, but human attention still isn’t up to catching them before they are released into the wild. The lower scenario represents a pivot into formal verification. Yes, there are still surprises of new kinds of bugs that sneak through. However, each time we learn about a new kind of bug, we strengthen the specification to rule out all bugs of that kind. With sound formal-verification tools, it then becomes impossible for those bugs to sneak through, even in the face of arbitrary programmer mistakes.
Even with formal verification, we still have the risk of serious zero-day bugs. However, if we arrange verification properly, then the zero-day window only opens for each new category of bug, not each individual programming mistake. We still worry that the bad guys get access to bug-finding software before the good guys and exploit a zero-day window, but there should just be many fewer windows that open. A window doesn’t open for each slip of the fingers by a programmer but instead only when an interestingly new kind of bug is discovered.
Formal verification has another asymmetric advantage over heuristic bug-finding: it allows us to move beyond having each development team suffer in isolation dealing with security problems, instead enabling significant shared effort toward blocking classes of vulnerabilities across all projects. It’s not that every project needs to discover and remediate a new bug category on its own. There are even opportunities for nearly instant updating of, say, all open-source projects’ security specifications, once a new bug category is discovered and announced by one project.
As an example, let’s use the classic security property of confidentiality within information flow. Some inputs to a system are considered to be secret, and their values should not be able to influence outputs that are considered public. Actually, there can be a lot more sophistication to the security policy than just considering inputs vs. outputs and secret vs. public values. Most generally, software developers define lattices of security levels. I wrote previously about how such concerns can be addressed for the case of compilers. We stepped through a series of increasing twists on top of the same basic confidentiality requirements: permitting nondeterminism in the specification opens up opportunities to leak secrets through choices that are left up to the implementation code, and allowing an eavesdropper to monitor timing can open up additional bad flows.
Just like software implementations, specifications should involve libraries of reusable notations. We can imagine a library for specification of secure information flow. The library can define a language for describing security levels, which each software project will use to specify its security policy, in addition to tagging inputs and outputs with levels. Then the library encodes how to connect that fundamental requirement to all sorts of different channels, including those based on nondeterminism and timing. In fact, the library starts out without coverage of those channels, but once it’s added, it becomes instantly applicable to all applications using the library. The situation is similar to what’s already in deployment with e.g. CodeQL query packs for pulling in new rules for static-analysis tools with weaker formal guarantees. Furthermore, if best practices are being followed through use of end-to-end verification, then infrastructure like compilers and operating systems can have its specifications expanded analogously, and the new application can have its specification stay linked with those of other components, for very efficient rollout of specified protection against a new attack family.
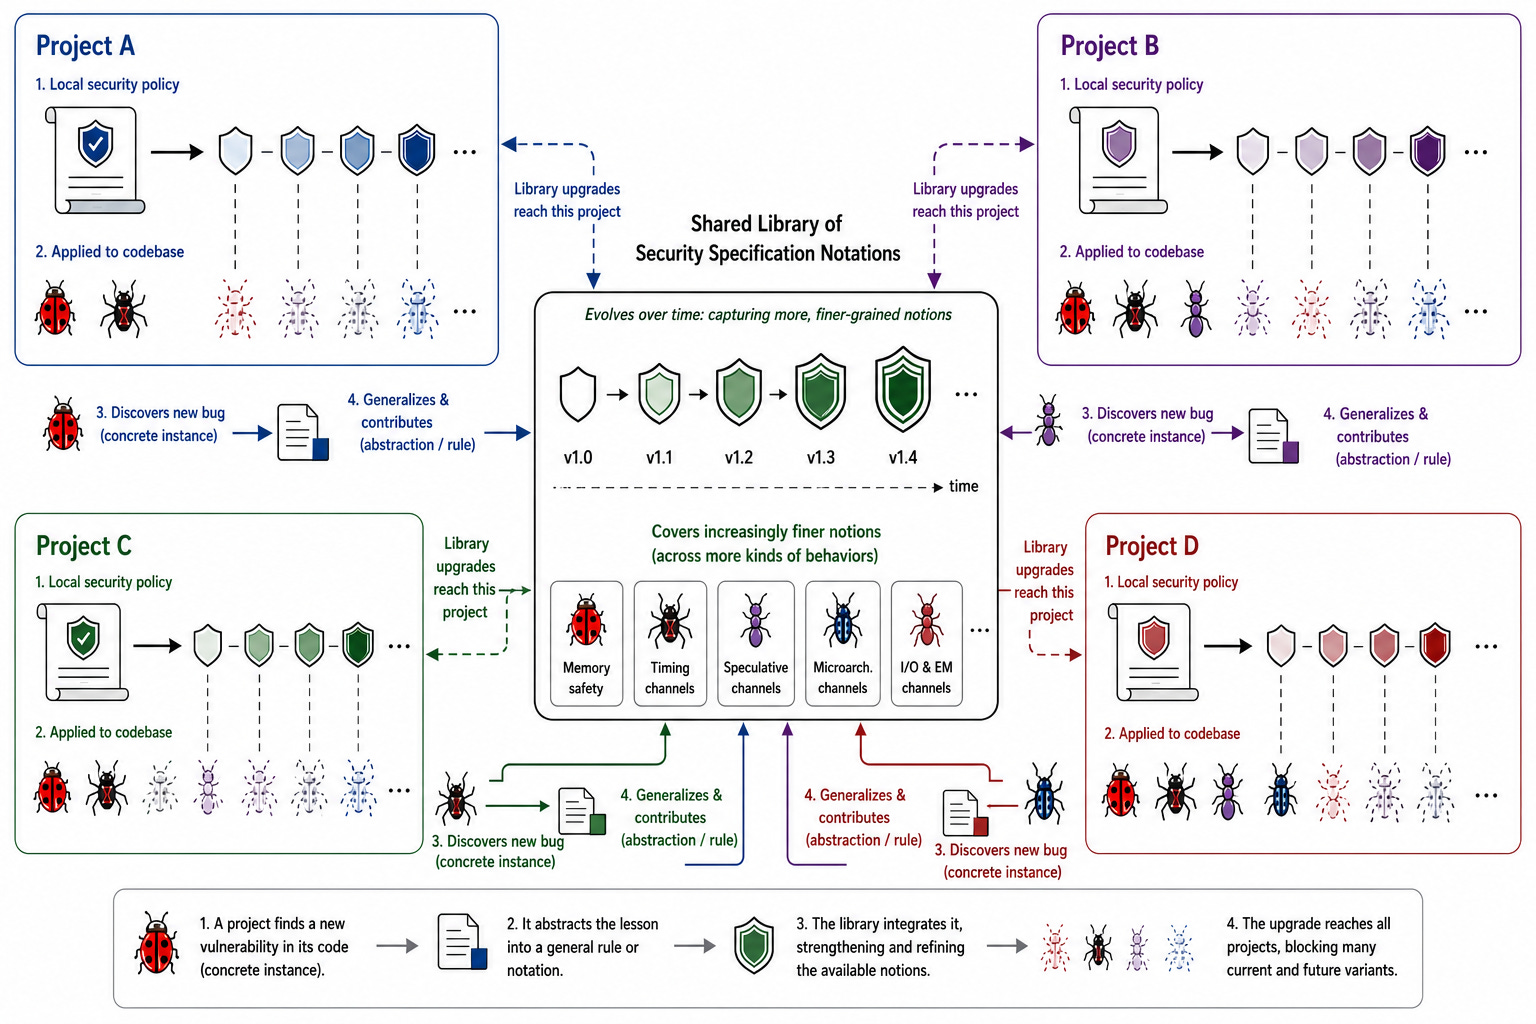
Now, updating a specification isn’t the whole story. Proofs about programs need to be extended to cover the new requirements. I wrote previously about how simplifying programming languages allows AI coding assistants to be more effective, including in meeting security requirements. If we simplify far enough, no explicit proof effort is required! I gave an example from our startup Nectry, which integrates checking of security policies into an agentic loop, so an AI writing software is getting constant feedback on security mistakes that it makes. (By the way, though it may not be obvious from the current Nectry web site both that we are doing this kind of formal methods and that we have a private beta running, in fact both are true, and folks at companies medium-sized and up can contact me if they think they might want to participate.)
I’ll also have much more to say in later articles about automating development of verified software, for broader classes of programs and specifications.
The Looming Challenge
I just discussed two main ways the rise of generative AI need not make software security more precarious than before – and can in fact help make security better (in the case of formal methods, through accelerating automatic proof-writing). The problem is that each method, LLM vulnerability scanners and strong formal verification, requires significant changes to software-development processes. Many legacy systems were developed before such technology was available, and we should worry about their security. Even new projects remain overwhelmingly carried out by teams not trained in these new methods.
What trajectory can we take toward getting these methods integrated into all software projects of nontrivial importance? My next article presents one framework with implications beyond security, considering how software maintenance should change when the cost of writing new code plummets.
The architecture you describe exists today for cloud security. Stave is an open-source AWS configuration verifier with a catalog of 3,000+ formal specifications (CEL predicates over configuration snapshots) https://github.com/sufield/stave. Each specification rules out a category of misconfiguration across every role, every account, every evaluation.